Generate Fake Logs for Testing Log Aggregation Platform: The Ultimate Guide
Generate realistic fake logs for testing log aggregation systems like Loki, ELK, and Splunk using Python, Docker, and Kubernetes step-by-step.
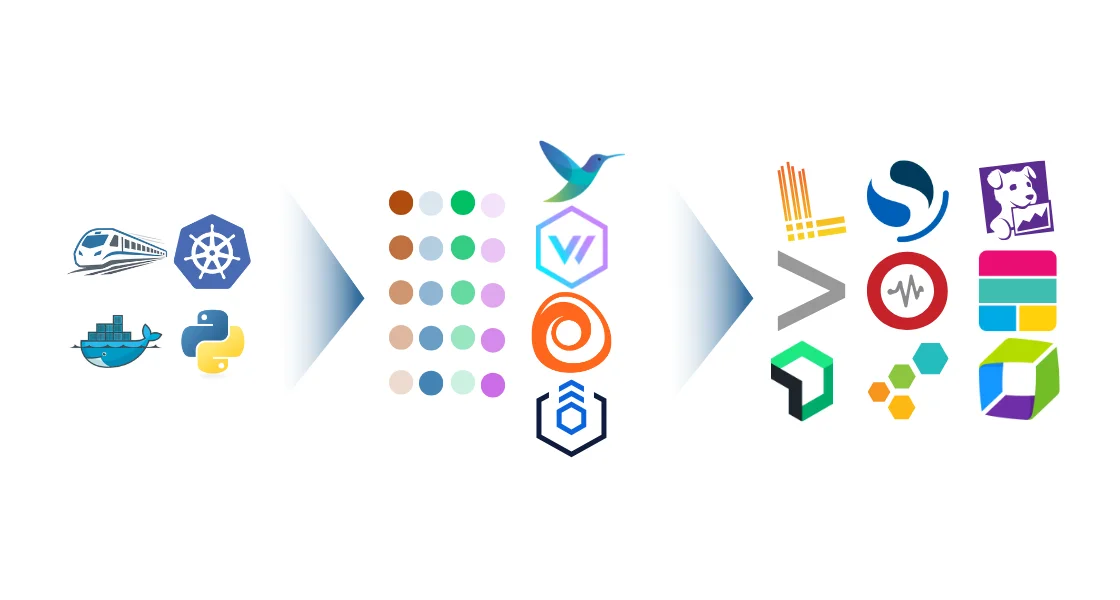
Testing log aggregation platforms like Loki, Elastic Stack, and Splunk requires realistic fake log data that mimics production environments. This comprehensive log generation guide covers the best tools and techniques for generating fake logs, complete with Docker and Kubernetes deployment examples.
Quick Start: Jump to fuzzy-train setup for immediate log generation or explore our Docker examples for containerized testing.
Log Generation Architecture Overview
graph TB
    subgraph "Log Generation Tools"
        A[fuzzy-train<br/>Multi-format]
        B[flog<br/>Apache-focused]
        C[Custom Scripts<br/>Pattern-specific]
    end

    subgraph "Output Methods"
        D[File Output<br/>Persistent storage]
        E[stdout Output<br/>Real-time streaming]
    end

    subgraph "Log Shipping Agents"
        F[Fluent-bit]
        G[Vector.dev]
        H[Grafana Alloy]
    end

    subgraph "Aggregation Platforms"
        I[Grafana Loki]
        J[Elastic Stack]
        K[Splunk]
    end

    subgraph "Monitoring & Analysis"
        L[Performance Metrics]
        M[Alert Testing]
    end

    A --> D
    B --> D
    C --> D
    A --> E
    B --> E
    C --> E

    D --> F
    D --> G
    D --> H
    E --> F
    E --> G
    E --> H

    F --> I
    F --> J
    F --> K
    G --> I
    G --> J
    G --> K
    H --> I
    H --> J
    H --> K

    I --> L
    J --> L
    K --> L
    I --> M
    J --> M
    K --> M

    style A fill:#e1f5fe
    style B fill:#f3e5f5
    style C fill:#e8f5e8
    style D fill:#fff3e0
    style E fill:#fce4ec
    style F fill:#e0f2f1
    style G fill:#f1f8e9
    style H fill:#f9fbe7
    style I fill:#e3f2fd
    style J fill:#f3e5f5
    style K fill:#e8f5e8
    style L fill:#fff8e1
    style M fill:#f3e5f5
Table of Contents
- Why Generate Fake Logs?
- Use Cases for Log Generation
- Best Tools for Log Generation
- Step-by-Step Implementation
- Log Shipping Configuration
- Advanced Log Generation Techniques
- Troubleshooting Log Generation
- Best Practices for Log Generation
- Conclusion
Why Generate Fake Logs?
Fake log generation is essential for modern DevOps and testing workflows. Log generation tools enable you to:
- Validate system performance under various load conditions without production data
- Test log parsing rules and filtering logic safely
- Develop monitoring dashboards with consistent, predictable data
- Train teams on log analysis tools and techniques
- Simulate error scenarios for alert testing
- Load test infrastructure before production deployment
Log Generation Workflow
flowchart TD
    A[Define Testing Requirements] --> B[Choose Log Format]
    B --> C[Select Generation Tool]
    C --> D[Configure Parameters]
    D --> E[Generate Fake Logs]
    E --> F[Verify Log Output]
    F --> G[Configure Log Shipping]
    G --> H[Test Aggregation Platform]
    H --> I[Validate Performance]
    I --> J[Monitor & Optimize]

    subgraph "Tool Selection"
        C1[fuzzy-train<br/>Multi-format, Docker-ready]
        C2[flog<br/>Fast, Apache-focused]
        C3[Custom Scripts<br/>Specific patterns]
    end

    subgraph "Output Options"
        E1[File Output<br/>Persistent storage]
        E2[stdout Output<br/>Real-time streaming]
        E3[Both Outputs<br/>Flexible testing]
    end

    subgraph "Validation Steps"
        H1[Parse Accuracy<br/>Format compliance]
        H2[Performance Metrics<br/>Throughput & latency]
        H3[Resource Usage<br/>CPU, memory, disk]
    end

    C --> C1
    C --> C2
    C --> C3
    E --> E1
    E --> E2
    E --> E3
    H --> H1
    H --> H2
    H --> H3

    style A fill:#e3f2fd
    style B fill:#e8f5e8
    style C fill:#fff3e0
    style D fill:#fce4ec
    style E fill:#f1f8e9
    style F fill:#e0f2f1
    style G fill:#f9fbe7
    style H fill:#fff8e1
    style I fill:#f3e5f5
    style J fill:#e1f5fe
Use Cases for Log Generation
Testing Log Aggregation Systems
Log aggregation testing is crucial for validating your observability stack:
- Cloud-Native Platforms: Grafana Loki, Elastic Stack (ELK), SigNoz, OpenSearch, Quickwit
- Enterprise Solutions: Splunk, Datadog, New Relic, Sumo Logic, Logz.io, Honeycomb
- Cloud Services: AWS CloudWatch, Azure Monitor, Google Cloud Logging, Papertrail
- Open Source: Rsyslog, Syslog-ng, Apache Flume, VictoriaLogs
- Performance Testing: Verify ingestion rates, query performance, and storage efficiency
- Scalability Testing: Test system behavior under high log volumes
Validating Log Shipping Agents
Log shipping validation ensures your data pipeline works correctly:
- Log Collectors: Fluent-bit, Grafana Alloy, Vector.dev, Promtail, Fluentd, Filebeat, Logstash, OpenTelemetry Collector, Telegraf
- Configuration Testing: Verify parsing rules, filtering, and routing logic
- Reliability Testing: Test agent behavior during network failures or high load
Development & Operations Use Cases
DevOps log testing scenarios include:
- Parser Development: Test regex patterns and log parsing rules
- Alert System Testing: Generate specific patterns to trigger monitoring alerts
- Dashboard Development: Create realistic data for visualization testing
- Load Testing: Simulate disk I/O and system resource usage
- Training & Demos: Provide realistic data for learning environments
Best Tools for Log Generation
Choosing the right log generation tool depends on your specific testing requirements. Here are the top-rated tools for fake log generation:
1. fuzzy-train - Versatile Log Generator
fuzzy-train is a versatile, zero-dependency fake log generator designed for observability testing and development. This Docker- and Kubernetes-ready tool runs anywhere, supports multiple formats, and includes complete drop-in flog argument compatibility.
Key Features (v3.0.0):
- Multiple Formats: JSON, logfmt, HTTP access, Apache (common/combined/error), BSD syslog (RFC3164), Syslog (RFC5424)
- Multi-Line Stack Traces (
--stack/--multiline): Built-in realistic stack traces for 8 languages (java,python,go,nodejs,dotnet,ruby,rust,php) to test multi-line aggregation in Fluent Bit, Vector.dev, and Promtail - Periodic Error Intervals (
-e, --error-interval): Emit simulated errors or stack traces at exact time intervals (e.g.1m,3m,5m) while regular traffic fills the gaps - Throughput & Volume Controls: Generate logs at steady byte rates (e.g.
0.5 MB/svia-r 2000,1.0 MB/svia-r 4000) or stop automatically after a target total volume (-b 1gbor-b 10gb) - Realistic Data: Optional faker-powered enrichment (realistic IPs, HTTP methods/paths, user-agents, hostnames, usernames, companies) auto-enabled when installed, with a zero-dependency fallback
- Smart Tracking:
trace_idautomatically adapts to local PID, Docker container ID, or Kubernetes 12-char pod name hash - Flexible Output: stdout, file, or both simultaneously; automatic log rotation (
--split-by) and gzip compression (--compressor.gz) - Fake Time Stepping: Spread timestamps across hours or days instantly (
--time-step 1s) without real-world waiting - Drop-in
flogCompatibility: Supports-d(--delay),-t(--type),-b(--bytes),-n(--number),-l(--loop),-w(--overwrite), and--duration
Python Script Usage:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
# Clone repository
git clone https://github.com/sagarnikam123/fuzzy-train
cd fuzzy-train

# Optional: install faker for enriched data (falls back gracefully to built-in generator if skipped)
pip install -r requirements.txt

# Default JSON logs (streaming to stdout)
python3 fuzzy-train.py

# Multi-line Java Spring Boot logs with stack traces every 1 minute
python3 fuzzy-train.py --stack java -e 1m -r 2 -z utc

# Multi-line Python tracebacks with 20% failure rate
python3 fuzzy-train.py --stack python --failure-rate 0.2 -r 5

# Stream at ~1.0 MB/sec until 1 GB is reached, then stop (-b 1gb)
python3 fuzzy-train.py -f json -r 4000 -b 1gb -o file --file 1gb-sample.log

# Stream at ~0.5 MB/sec until 10 GB is reached, then stop (-b 10gb)
python3 fuzzy-train.py -f json -r 2000 -b 10gb -o file --file 10gb-sample.log

# Split a 10 GB run into ten 1 GB rotated files
python3 fuzzy-train.py -f json -r 5000 -b 10gb -p 1gb -o file --file 10gb-split.log

# Apache common logs to file with custom message length
python3 fuzzy-train.py \
    --min-log-length 100 \
    --max-log-length 200 \
    --lines-per-second 5 \
    --log-format apache-common \
    --time-zone utc \
    --output file

# HTTP access logs with 10% 500 errors and exponential arrival (realistic bursts)
python3 fuzzy-train.py -f http --failure-rate 0.1 --arrival exponential -r 10 -n 100

# Fast Historical Backfill: 10,000 logs stamped 1s apart (~2.7 hours of history) generated in ~5s
python3 fuzzy-train.py -f json -n 10000 -s 1s -r 2000 -z utc -o historical.log
Docker Usage:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
# Quick start with defaults (v3.0.0 / latest)
docker run --rm sagarnikam123/fuzzy-train:latest

# Multi-line stack trace generator (Java)
docker run -d --name log-streamer-java \
  sagarnikam123/fuzzy-train:latest \
  --stack java -e 1m -r 2

# Stream at 1.0 MB/sec until 1 GB is written, then exit cleanly
docker run --rm -v "$(pwd)/logs":/logs sagarnikam123/fuzzy-train:latest \
  -f json -r 4000 -b 1gb -o file --file /logs/benchmark-1gb.log

# Run in background with structured JSON at 500 lines/sec
docker run -d --name fuzzy-train-json \
  sagarnikam123/fuzzy-train:latest \
  -f json -r 500 -z utc
Kubernetes Deployment (Dedicated fuzzy-train Namespace):
All manifests automatically create the fuzzy-train namespace so your cluster’s default namespace stays clean:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
# 🚀 1. All-in-One Observability Stack (4 workloads: Java multiline, JSON, HTTP, and DaemonSet)
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/all-in-one-namespace-stack.yaml

# ☸️ 2. Per-Node Multi-Line Stack Trace DaemonSet (runs on all nodes, emits errors every 1m)
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/daemonset-per-node-multiline.yaml

# ☸️ 3. Per-Node JSON DaemonSet (structured logs on every node, 1m error interval)
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/daemonset-per-node-json.yaml

# ⏱️ 4. Volume Benchmark Job: Streams 1.0 MB/sec until 1 GB is reached, then terminates
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/volume-benchmark-job.yaml

# View running pods in the dedicated namespace
kubectl get pods -n fuzzy-train

# Tail Java multi-line logs live
kubectl logs -n fuzzy-train -l app=fuzzy-train-multiline -f

# Clean up all resources in one command:
kubectl delete namespace fuzzy-train
2. flog - Fast Log Generator
flog is a high-performance fake log generator optimized for common log formats including Apache, syslog, and JSON. This Go-based log generation tool is ideal for testing log streams and data pipelines with minimal resource overhead.
Supported Formats: apache_common (default), apache_combined, apache_error, rfc3164 (syslog), rfc5424 (syslog), json Output Types: stdout (default), log (file), gz (gzip compressed)
Tool Comparison Matrix
graph LR
    subgraph "fuzzy-train (v3.0.0)"
        A1[Multi-format & Stacks<br/>JSON, Logfmt, Apache, Syslog<br/>8-Lang Multi-line Stack Traces]
        A2[Docker & K8s Ready<br/>Self-contained namespace<br/>DaemonSets & Jobs]
        A3[Smart Tracking<br/>trace_id, PID, Container ID, Pod Hash]
        A4[Throughput & Volume Caps<br/>0.5 - 1.0 MB/s, 1GB/10GB limits]
        A5[Alert & Anomaly Simulation<br/>--failure-rate & -e 1m/3m intervals]
        A6[Drop-in flog Parity<br/>-d delay, -t type, -b bytes, -l loop]
    end

    subgraph "flog"
        B1[Apache Focused<br/>Web server logs]
        B2[High Performance<br/>Go-based, single binary]
        B3[Compression Support<br/>gzip output]
        B4[Size-based Generation<br/>MB/GB targets]
        B5[Continuous Mode<br/>Loop generation]
    end

    subgraph "Use Case Decision"
        C1[<b>fuzzy-train</b> :<br/>• Multi-format & Multi-line exceptions<br/>• Periodic error intervals (1m/3m)<br/>• K8s DaemonSets / Microservices mesh<br/>• Throughput & target volume limits<br/>• Realistic faker data & drop-in flog flags]

        C2[<b>flog</b> :<br/>• Prefer a single Go binary<br/>• Max raw throughput<br/>• Simple Apache-centric workflows]
    end

    style A1 fill:#e1f5fe
    style A2 fill:#e1f5fe
    style A3 fill:#e1f5fe
    style A4 fill:#e1f5fe
    style A5 fill:#e1f5fe
    style A6 fill:#e1f5fe
    style B1 fill:#f3e5f5
    style B2 fill:#f3e5f5
    style B3 fill:#f3e5f5
    style B4 fill:#f3e5f5
    style B5 fill:#f3e5f5
    style C1 fill:#e8f5e8
    style C2 fill:#fff3e0
Installation Options:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
# Using go install (recommended)
go install github.com/mingrammer/flog

# Using Homebrew
brew tap mingrammer/flog
brew install flog

# Using pre-built binary
# macOS
curl -O -L "https://github.com/mingrammer/flog/releases/download/v0.4.4/flog_0.4.4_darwin_amd64.tar.gz"
tar -xvzf flog_0.4.4_darwin_amd64.tar.gz
cd flog_0.4.4_darwin_amd64

# Linux
curl -O -L "https://github.com/mingrammer/flog/releases/download/v0.4.4/flog_0.4.4_linux_amd64.tar.gz"
tar -xvzf flog_0.4.4_linux_amd64.tar.gz
cd  flog_0.4.4_linux_amd64

chmod +x ./flog
sudo mv ./flog /usr/local/bin/
Command Line Usage:
1
2
3
4
5
6
7
8
9
10
11
# Generate (-n) 1000 logs to stdout (default)
flog

# Generate logs with (-s) time interval and (-d) delay
flog -s 10s -n 200 -d 3s

# Apache combined (-f) format with (-w) overwrite to (-o) output file
flog -t log -f apache_combined -w -o apache.log

# Continuous generation with (--loop) mode
flog -f rfc3164 -l
Advanced Options:
1
2
3
4
5
6
7
8
# Generate logs by size instead of line count
flog -b 10485760 -f json -o large.log

# Split logs every 1MB with gzip compression
flog -t gz -o log.gz -b 10485760 -p 1048576

# Generate logs with path structure
flog -t log -f apache_combined -o web/log/apache.log -n 5000
Docker Usage:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
# Basic Docker run (interactive)
docker run -it --rm mingrammer/flog

# Generate logs to stdout with custom parameters
docker run --rm mingrammer/flog -f apache_combined -n 500

# Generate logs to file with volume mount
docker run --rm -v "$(pwd)":/logs mingrammer/flog -t log -o /logs/apache.log -n 1000

# Continuous log generation in background
docker run -d --name flog-generator mingrammer/flog -f json -l

# High-volume generation with gzip compression
docker run --rm -v "$(pwd)":/logs mingrammer/flog -t gz -o /logs/large.log.gz -b 50MB

# Cleanup running containers
docker stop $(docker ps -q --filter ancestor=mingrammer/flog)
docker rm $(docker ps -aq --filter ancestor=mingrammer/flog)
Step-by-Step Implementation
Follow this log generation implementation guide to set up fake log generation for your testing environment:
Step 1: Choose Your Log Format
Selecting the right log format for testing is crucial for realistic log aggregation testing:
- Apache Common / Combined: Web server testing
- HTTP access (
--log-format http): method/url/status/duration lines for alert and parser demos - JSON: Modern microservices
- Syslog: System-level testing
- Logfmt: Structured key-value logs
Step 2: Set Up Log Generation with fuzzy-train
Implement Docker-based log generation using fuzzy-train for scalable testing:
Using Docker (Recommended)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
# Generate JSON logs to file
docker run -d --name fuzzy-train-generator \
  -v /tmp/logs:/logs \
  sagarnikam123/fuzzy-train:latest \
  --log-format JSON \
  --lines-per-second 5 \
  --output file \
  --file /logs/fuzzy-train.log

# Generate Apache combined logs
docker run -d --name apache-log-generator \
  -v /tmp/logs:/logs \
  sagarnikam123/fuzzy-train:latest \
  --log-format "apache combined" \
  --lines-per-second 10 \
  --output file \
  --file /logs/apache.log
Using Python Script
1
2
3
4
5
6
7
8
9
10
# Clone and setup fuzzy-train
git clone https://github.com/sagarnikam123/fuzzy-train
cd fuzzy-train

# Generate logs to file
python3 fuzzy-train.py \
  --log-format JSON \
  --lines-per-second 5 \
  --output file \
  --file $HOME/data/log/logger/fuzzy-train.log
Step 3: Verify Log Generation
1
2
3
4
5
# Check generated logs
tail -f /tmp/logs/fuzzy-train.log

# Monitor log generation rate
watch "wc -l /tmp/logs/fuzzy-train.log" # brew install watch
Log Shipping Configuration
Configure log shipping agents to collect and forward your generated fake logs to aggregation platforms:
Fluent-bit Configuration
1
fluent-bit --config=fluent-bit-local-fs-json-loki.yaml
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
# fluent-bit-local-fs-json-loki.yaml

service:
  log_level: info    # warn
  http_server: on
  http_listen: 0.0.0.0
  http_port: 2020

parsers:    # adjust according to your log format
  - name: json
    format: json
    time_key: timestamp
    time_format: "%Y-%m-%dT%H:%M:%S.%LZ"
    time_keep: on

pipeline:
  inputs:
    - name: tail
      path: /tmp/logs/*.log    # adjust as per your .log file location
      read_from_head: false
      refresh_interval: 10
      ignore_older: 1h
      tag: local.*
      parser: json

  outputs:
    - name: loki
      match: '*'
      host: 127.0.0.1    # change to your Loki instance host or IP
      port: 3100    # change to your Loki instance port
      labels: service_name=fluent-bit, source=fuzzy-train-log
Vector.dev Configuration
1
2
vector validate config/vector-local-fs-json-loki.yaml
vector --config=config/vector-local-fs-json-loki.yaml
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
# vector-local-fs-json-loki.yaml

data_dir: $HOME/data/vector

sources:
  fuzzy_logs:
    type: file
    include:
      - /tmp/logs/*.log    # adjust as per your .log file location
    read_from: beginning
    encoding:
      charset: utf-8

transforms:
  parse_logs:
    type: remap
    inputs:
      - fuzzy_logs
    source: |
      . = parse_json!(.message)

sinks:
  loki_sink:
    type: loki
    inputs:
      - parse_logs
    endpoint: http://127.0.0.1:3100    # change to your Loki instance endpoint
    encoding:
      codec: json
    healthcheck:
      enabled: true
    labels:
      service_name: fuzzy-train
      source: fuzzy-train-log

api:    # optional
  enabled: true
  address: 127.0.0.1:8686
  playground: true
Grafana Alloy Configuration
1
2
alloy run config/alloy-local-fs-json-loki.alloy
# Visit UI - http://127.0.0.1:12345/
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
# alloy-local-fs-json-loki.alloy

livedebugging {
  enabled = true
}

local.file_match "local_files" {
    path_targets = [{"__path__" = "/tmp/logs/*.log", "job" = "alloy", "hostname" = constants.hostname}]
    sync_period  = "5s"
}

loki.source.file "log_scrape" {
    targets    = local.file_match.local_files.targets
    forward_to = [loki.write.local_loki.receiver]
    tail_from_end = true
}

loki.write "local_loki" {
  endpoint {
    url = "http://127.0.0.1:3100/loki/api/v1/push"
  }
}
Advanced Log Generation Techniques
Implement sophisticated log generation patterns for comprehensive testing scenarios:
Volume Calculation Guide
Understanding log generation volume calculations helps optimize your testing infrastructure:
Log Encoding Information:
- Character Encoding: UTF-8
- Basic ASCII characters: 1 byte each (letters, numbers, punctuation)
- Newlines: 1 byte each (
\n) - JSON overhead: ~50-80 bytes per log (timestamp, level, trace_id, etc.)
Formula:
1
Data Rate (MB/sec) = (Average Log Size in bytes) × (Lines per second) × (Number of instances) ÷ 1,048,576
Note: 1,048,576 is the number of bytes in 1 MB (1024 × 1024 bytes)
Example: Generate 10 MB/sec
To generate 10 MB/sec of log data, you need to calculate the required lines per second based on your average log size:
Option 1: Single high-volume instance - Average log size of ~200 bytes (150 characters + JSON overhead + newline). Required rate: 10 MB/sec ÷ 200 bytes = ~52,428 lines/sec. Use parameters: –lines-per-second 52428 –min-log-length 130 –max-log-length 170
Option 2: Multiple moderate instances (recommended) - 10 instances × 5,243 lines/sec each = 52,430 total lines/sec. Per instance parameters: –lines-per-second 5243 –min-log-length 130 –max-log-length 170
Option 3: Many small instances - 50 instances × 1,049 lines/sec each = 52,450 total lines/sec. Per instance parameters: –lines-per-second 1049 –min-log-length 130 –max-log-length 170
Generating Target Throughput (0.5 MB/s, 1.0 MB/s) & Total Volume Caps (1 GB, 10 GB)
Observability engineers often need to test storage rate limiters or evaluate query performance over a bounded dataset (e.g. “Stream at exactly 1 MB/sec until 1 GB is reached, then stop”):
Throughput Pacing Cheat-Sheet:
| Desired Throughput | Log Format | Average Line Size | Recommended -r Flag |
|---|---|---|---|
| 0.5 MB/sec (~512 KB/s) | json | ~250 B | -r 2000 |
| 1.0 MB/sec (~1024 KB/s) | json | ~250 B | -r 4000 |
| 0.5 MB/sec | apache-combined | ~300 B | -r 1700 |
| 1.0 MB/sec | apache-combined | ~300 B | -r 3400 |
| 0.5 MB/sec | logfmt | ~175 B | -r 2900 |
| 1.0 MB/sec | logfmt | ~175 B | -r 5800 |
Pro-Tip: Make 1 Line = Exactly 1 KB:
Pass--min-log-length 900 --max-log-length 900. With JSON overhead, each log line is exactly 1,024 bytes (1 KB). This provides a 1:1 match:
- 0.5 MB/sec:
-r 500- 1.0 MB/sec:
-r 1000
Practical Recipes:
1
2
3
4
5
6
7
8
9
10
11
12
# 1. Stream at 1.0 MB/sec until 1 GB is reached (~17 minutes), then exit:
python3 fuzzy-train.py -f json -r 4000 -b 1gb -o file --file test-1gb.log

# 2. Stream at 0.5 MB/sec until 10 GB is reached (~5.6 hours), then exit:
python3 fuzzy-train.py -f json -r 2000 -b 10gb -o file --file test-10gb.log

# 3. Generate 10 GB in Docker split into ten 1 GB rotated files:
docker run --rm -v "$(pwd)/logs":/logs sagarnikam123/fuzzy-train:latest \
  -f json -r 5000 -b 10gb -p 1gb -o file --file /logs/benchmark.log

# 4. Kubernetes Job: Generate 1 GB at 1.0 MB/sec in the 'fuzzy-train' namespace and complete:
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/volume-benchmark-job.yaml
Volume Calculation Visualization
graph TD
    subgraph "Volume Formula"
        F[Data Rate MB/sec = <br/>Log Size × Lines/sec × Instances ÷ 1,048,576]
    end

    subgraph "10 MB/sec Examples"
        E1[Single Instance<br/>52,428 lines/sec]
        E2[10 Instances<br/>5,243 lines/sec each]
        E3[50 Instances<br/>1,049 lines/sec each]
    end

    subgraph "Common Targets"
        V1[1 MB/sec<br/>~7,000 lines/sec]
        V2[5 MB/sec<br/>~21,000 lines/sec]
        V3[100 MB/sec<br/>~300,000 lines/sec]
    end

    subgraph "Resource Impact"
        R1[CPU: Higher rate = More usage]
        R2[Memory: Larger logs = More memory]
        R3[Disk: File output = I/O pressure]
    end

    F --> E1
    F --> E2
    F --> E3
    F --> V1
    F --> V2
    F --> V3
    E1 --> R1
    E2 --> R2
    E3 --> R3

    style F fill:#e3f2fd
    style E1 fill:#e8f5e8
    style E2 fill:#fff3e0
    style E3 fill:#fce4ec
    style V1 fill:#f1f8e9
    style V2 fill:#e0f2f1
    style V3 fill:#f9fbe7
    style R1 fill:#ffebee
    style R2 fill:#fff3e0
    style R3 fill:#e8f5e8
High-Volume Log Generation
Implement high-volume log generation for performance testing and load testing scenarios:
Docker High-Volume Generation:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
# Clean up any existing log files
rm -f /tmp/logs/*
mkdir -p /tmp/logs

# Generate 100 logs per second for load testing
# Volume generated: 100 lines/sec × ~150 bytes = ~14.3 KB/sec (0.014 MB/sec)
docker run -d --name high-volume-generator \
  -v /tmp/logs:/logs \
  sagarnikam123/fuzzy-train:latest \
  --lines-per-second 100 \
  --log-format JSON \
  --output file \
  --file /logs/high-volume.log

# Multiple containers for extreme load
for i in {1..5}; do
  docker run -d --name volume-gen-$i \
    -v /tmp/logs:/logs \
    sagarnikam123/fuzzy-train:latest \
    --lines-per-second 50 \
    --log-format JSON \
    --output file \
    --file /logs/volume-$i.log
done

# Cleanup when done testing - takes time - wait & have patience!
for i in {1..5}; do
  docker stop volume-gen-$i
  docker rm volume-gen-$i
done
📊 Volume Calculation Breakdown
| Container | Lines/sec | Bytes/line | Volume/sec | MB/sec |
|---|---|---|---|---|
| volume-gen-1 | 50 | ~150 | 7.1 KB | 0.007 |
| volume-gen-2 | 50 | ~150 | 7.1 KB | 0.007 |
| volume-gen-3 | 50 | ~150 | 7.1 KB | 0.007 |
| volume-gen-4 | 50 | ~150 | 7.1 KB | 0.007 |
| volume-gen-5 | 50 | ~150 | 7.1 KB | 0.007 |
| TOTAL | 250 | ~150 | 🔥 35.7 KB | 0.035 |
💡 Total Volume Generated: 5 containers × 7.1 KB/sec = 35.7 KB/sec (0.035 MB/sec)
Error Pattern Simulation
Simulate realistic error patterns for alert testing and log aggregation — prefer a controlled ERROR/HTTP 500 mix over guessing from volume alone.
Flag recipes (--failure-rate, -f http) are in fuzzy-train examples above. Here: write files and spot-check.
1
2
3
4
5
6
7
8
9
mkdir -p /tmp/logs

# ~20% ERROR in JSON (level-based alerts)
docker run --rm -v /tmp/logs:/logs sagarnikam123/fuzzy-train:latest \
  --failure-rate 0.2 --lines-per-second 1000 \
  --log-format JSON --output file --file /logs/errors-mixed.log -n 200

# Spot-check ERROR count (expect roughly ~40 of 200)
grep -c '"level": "ERROR"' /tmp/logs/errors-mixed.log
Volume burst (stress ingestion rate): omit --failure-rate if you only care about throughput; add it when the burst should also contain ERROR/500 lines.
1
2
3
4
5
6
7
# High line rate for 2 minutes (ingestion stress only — no failure-rate)
docker run --rm -v /tmp/logs:/logs sagarnikam123/fuzzy-train:latest \
  --lines-per-second 5000 \
  --min-log-length 150 --max-log-length 200 \
  --log-format JSON --output file --file /logs/volume-burst.log &
sleep 120
docker stop $(docker ps -q --filter ancestor=sagarnikam123/fuzzy-train:latest) 2>/dev/null || true
Multi-Service Log Simulation
Create multi-service log generation scenarios using Docker Compose for microservices testing:
Docker Compose Multi-Service Setup:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
# docker-compose.yml
# Docker Compose - File Output (Default)
# Generates logs to files in ./logs/ directory for testing log file scrapers
# Usage: docker-compose up
# View logs: tail -f logs/[service-name].log
# For stdout output, use: docker-compose -f docker-compose-stdout.yml up

services:
  auth-service:
    # Volume generated: 2,000 lines/sec × ~200 bytes (150 chars + JSON overhead) = ~381 KB/sec (0.38 MB/sec)
    image: sagarnikam123/fuzzy-train:latest
    command:
      - --lines-per-second
      - "2000"
      - --min-log-length
      - "120"
      - --max-log-length
      - "180"
      - --log-format
      - JSON
      - --time-zone
      - UTC
      - --output
      - file
      - --file
      - /logs/auth-service.log
      - --trace-id-type
      - integer
    volumes:
      - ./logs:/logs
    container_name: auth-logs

  payment-service:
    # Volume generated: 1,500 lines/sec × ~175 bytes (125 chars + logfmt overhead) = ~251 KB/sec (0.25 MB/sec)
    image: sagarnikam123/fuzzy-train:latest
    command:
      - --lines-per-second
      - "1500"
      - --min-log-length
      - "100"
      - --max-log-length
      - "150"
      - --log-format
      - logfmt
      - --time-zone
      - UTC
      - --output
      - file
      - --file
      - /logs/payment-service.log
      - --trace-id-type
      - integer
    volumes:
      - ./logs:/logs
    container_name: payment-logs

  user-service:
    # Volume generated: 1,000 lines/sec × ~300 bytes (250 chars + Apache overhead) = ~286 KB/sec (0.29 MB/sec)
    image: sagarnikam123/fuzzy-train:latest
    command:
      - --lines-per-second
      - "1000"
      - --min-log-length
      - "200"
      - --max-log-length
      - "300"
      - --log-format
      - apache combined
      - --time-zone
      - UTC
      - --output
      - file
      - --file
      - /logs/user-service.log
      - --trace-id-type
      - integer
    volumes:
      - ./logs:/logs
    container_name: user-logs
Running the Docker Compose Setup:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
# Clean up any existing log files
rm -f logs/* 2>/dev/null || true

# Create logs directory
mkdir -p logs

# Start all services in background
docker compose up -d           # or legacy: docker-compose up -d

# View running services
docker compose ps

# Check generated log files
ls -la logs/

# Monitor log files (since containers write to files, not stdout)
tail -f logs/auth-service.log
tail -f logs/payment-service.log
tail -f logs/user-service.log

# Monitor all log files simultaneously
tail -f logs/*.log

# Stop all services
docker compose down

# Tip: To run a 4-tier microservice simulation with Java multi-line stack traces, use:
# docker compose -f examples/docker/docker-compose-observability.yml up -d
📊 Volume Calculation Reference
Docker Compose Multi-Service Volume Breakdown
| Service | Format | Lines/sec | Bytes/line | Volume/sec | MB/hour |
|---|---|---|---|---|---|
| auth-service | JSON | 2,000 | ~200 | 381 KB | 1,372 MB |
| payment-service | logfmt | 1,500 | ~175 | 251 KB | 904 MB |
| user-service | Apache | 1,000 | ~300 | 286 KB | 1,030 MB |
| 🔥 TOTAL | Mixed | 4,500 | ~225 avg | 🚀 918 KB | 3,306 MB |
Volume Scaling Examples
| Scenario | Total Lines/sec | Volume/sec | Volume/hour | Volume/day |
|---|---|---|---|---|
| Light Testing | 100 | 20 KB | 72 MB | 1.7 GB |
| Medium Load | 1,000 | 200 KB | 720 MB | 17.3 GB |
| Heavy Load | 4,500 | 918 KB | 3.3 GB | 79.4 GB |
| Stress Test | 10,000 | 2.0 MB | 7.2 GB | 172.8 GB |
Storage Planning Guide
💾 Disk Space Requirements:
- 1 hour testing: ~3.3 GB (heavy load)
- 8 hour workday: ~26.4 GB (heavy load)
- 24 hour continuous: ~79.4 GB (heavy load)
- 1 week continuous: ~556 GB (heavy load)
⚠️ Important: Add 20-30% buffer for log rotation and compression overhead.
Multi-Service Log Generation Architecture
graph TB
    subgraph "Docker Compose Services"
        AUTH[auth-service<br/>2,000 logs/sec<br/>~381 KB/sec]
        PAY[payment-service<br/>1,500 logs/sec<br/>~251 KB/sec]
        USER[user-service<br/>1,000 logs/sec<br/>~286 KB/sec]
    end

    subgraph "Log Output"
        AUTH --> AUTH_LOG[auth-service.log<br/>JSON format]
        PAY --> PAY_LOG[payment-service.log<br/>Logfmt format]
        USER --> USER_LOG[user-service.log<br/>Apache combined]
    end

    subgraph "Volume Mounts"
        AUTH_LOG --> VOL[./logs volume<br/>Host directory]
        PAY_LOG --> VOL
        USER_LOG --> VOL
    end

    subgraph "Total Generation"
        TOTAL[Total Volume<br/>~918 KB/sec<br/>0.92 MB/sec]
        AUTH --> TOTAL
        PAY --> TOTAL
        USER --> TOTAL
    end

    subgraph "Log Shipping Options"
        VOL --> FLUENT[Fluent-bit<br/>Tail input]
        VOL --> VECTOR[Vector.dev<br/>File source]
        VOL --> ALLOY[Grafana Alloy<br/>Local file match]
    end

    subgraph "Aggregation Platforms"
        FLUENT --> LOKI[Grafana Loki]
        VECTOR --> LOKI
        ALLOY --> LOKI

        FLUENT --> ELK[Elastic Stack]
        VECTOR --> ELK
        ALLOY --> ELK
    end

    style AUTH fill:#e1f5fe
    style PAY fill:#f3e5f5
    style USER fill:#e8f5e8
    style AUTH_LOG fill:#fff3e0
    style PAY_LOG fill:#fce4ec
    style USER_LOG fill:#f1f8e9
    style VOL fill:#e0f2f1
    style TOTAL fill:#f9fbe7
    style FLUENT fill:#fff8e1
    style VECTOR fill:#e3f2fd
    style ALLOY fill:#f3e5f5
    style LOKI fill:#e8f5e8
    style ELK fill:#fff3e0
Kubernetes DaemonSet for Cluster-Wide Generation
Deploy cluster-wide log generation using Kubernetes DaemonSet to test node-level log collectors (Fluent Bit, Vector, Promtail) tailing /var/log/pods:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
# daemonset-per-node-multiline.yaml
apiVersion: v1
kind: Namespace
metadata:
  name: fuzzy-train
---
apiVersion: apps/v1
kind: DaemonSet
metadata:
  name: fuzzy-train-node-multiline
  namespace: fuzzy-train
spec:
  selector:
    matchLabels:
      app: fuzzy-train-node-multiline
  template:
    metadata:
      labels:
        app: fuzzy-train-node-multiline
    spec:
      tolerations:
        - operator: Exists      # Deploy to ALL nodes including control-plane
      containers:
      - name: generator
        image: sagarnikam123/fuzzy-train:latest
        args:
          - "--stack"
          - "java"              # Realistic multi-line stack traces
          - "--error-interval"
          - "1m"                # Emits a multi-line exception every 1 minute
          - "--lines-per-second"
          - "2"
          - "--time-zone"
          - "utc"
Deploy and Manage DaemonSets:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
# Option A: Deploy Multi-Line Stack Trace DaemonSet (Java errors every 1m)
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/daemonset-per-node-multiline.yaml

# Option B: Deploy Structured JSON DaemonSet (errors every 1m)
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/daemonset-per-node-json.yaml

# Check DaemonSet status in fuzzy-train namespace
kubectl get daemonset -n fuzzy-train

# View running pods on all nodes
kubectl get pods -n fuzzy-train -o wide

# View logs from all node pods simultaneously
kubectl logs -n fuzzy-train -l app=fuzzy-train-node-multiline -f --max-log-requests=10

# Cleanup entire namespace and workloads in one command:
kubectl delete namespace fuzzy-train
Kubernetes Cluster-Wide Log Generation
graph TB
    subgraph "Kubernetes Cluster"
        NODE1[Node 1<br/>fuzzy-train pod<br/>10 logs/sec]
        NODE2[Node 2<br/>fuzzy-train pod<br/>10 logs/sec]
        NODE3[Node 3<br/>fuzzy-train pod<br/>10 logs/sec]
        NODE4[Node 4<br/>fuzzy-train pod<br/>10 logs/sec]
    end

    subgraph "Log Generation per Node"
        NODE1 --> LOG1[stdout logs<br/>JSON format<br/>~1.6 KB/sec]
        NODE2 --> LOG2[stdout logs<br/>JSON format<br/>~1.6 KB/sec]
        NODE3 --> LOG3[stdout logs<br/>JSON format<br/>~1.6 KB/sec]
        NODE4 --> LOG4[stdout logs<br/>JSON format<br/>~1.6 KB/sec]
    end

    subgraph "Total Cluster Volume"
        TOTAL[Total Volume<br/>40 logs/sec<br/>~6.4 KB/sec]
        LOG1 --> TOTAL
        LOG2 --> TOTAL
        LOG3 --> TOTAL
        LOG4 --> TOTAL
    end

    subgraph "Log Collection Options"
        TOTAL --> PROMTAIL[Promtail<br/>DaemonSet]
        TOTAL --> FLUENT[Fluent-bit<br/>DaemonSet]
        TOTAL --> VECTOR[Vector.dev<br/>DaemonSet]
    end

    subgraph "Aggregation Platforms"
        PROMTAIL --> LOKI[Grafana Loki]
        FLUENT --> LOKI
        VECTOR --> LOKI

        PROMTAIL --> ELK[Elastic Stack]
        FLUENT --> ELK
        VECTOR --> ELK
    end

    subgraph "Scaling Options"
        SCALE1[High Volume: 50 logs/sec per node<br/>Total: 200 logs/sec ~32 KB/sec<br/>Daily: ~2.8 GB]
        SCALE2[Low Volume: 1 log/sec per node<br/>Total: 4 logs/sec ~0.64 KB/sec<br/>Daily: ~55 MB]
    end

    TOTAL --> SCALE1
    TOTAL --> SCALE2

    style NODE1 fill:#e1f5fe
    style NODE2 fill:#e1f5fe
    style NODE3 fill:#e1f5fe
    style NODE4 fill:#e1f5fe
    style LOG1 fill:#f3e5f5
    style LOG2 fill:#f3e5f5
    style LOG3 fill:#f3e5f5
    style LOG4 fill:#f3e5f5
    style TOTAL fill:#e8f5e8
    style PROMTAIL fill:#fff3e0
    style FLUENT fill:#fce4ec
    style VECTOR fill:#f1f8e9
    style LOKI fill:#e0f2f1
    style ELK fill:#f9fbe7
    style SCALE1 fill:#ffebee
    style SCALE2 fill:#fff8e1
Tweaking Volume and Rate:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
# High-volume stress testing on all nodes:
# Volume per node: 50 lines/sec × ~350 bytes = ~17 KB/sec (~1 MB/min per node)
# Edit args in examples/k8s/daemonset-per-node-json.yaml:
# - "--lines-per-second"
# - "50"
# - "--min-log-length"
# - "200"
# - "--max-log-length"
# - "500"

# Adjust periodic error frequency:
# Set -e 1m (every 1 min) or -e 3m (every 3 mins) to test anomaly alert thresholds

# Apply changes to fuzzy-train namespace:
kubectl apply -f https://raw.githubusercontent.com/sagarnikam123/fuzzy-train/refs/heads/main/examples/k8s/daemonset-per-node-json.yaml
Troubleshooting Log Generation
Resolve common log generation issues and optimize performance:
Common Log Generation Issues
Container Permission Issues:
1
2
3
# Fix volume permissions
sudo chown -R $USER:$USER /tmp/logs
chmod 755 /tmp/logs
High CPU Usage:
1
2
3
# Reduce log generation rate
docker run --cpus="0.5" --memory="256m" sagarnikam123/fuzzy-train:latest \
  --lines-per-second 10
Log Shipping Agent Not Reading Files:
1
2
3
4
# Check file permissions and paths
ls -la /tmp/logs/
# Verify agent configuration
tail -f /var/log/fluent-bit.log
Log Generation Performance Optimization
Optimize for High Volume:
- Use SSD storage for log files
- Increase file system buffer sizes
- Monitor disk I/O and memory usage
- Use log rotation to prevent disk space issues
Custom Error Pattern Script
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
#!/usr/bin/env python3
# simulate_error_patterns.py

import subprocess
import time

def simulate_error_patterns():
    # rate = lines/sec; failure = P(ERROR) / P(HTTP 500) for that phase
    patterns = [
        {"rate": 2, "duration": 60, "format": "JSON", "failure": 0.02},    # Normal: low ERROR mix
        {"rate": 20, "duration": 30, "format": "JSON", "failure": 0.4},    # Error spike: volume + high ERROR
        {"rate": 5, "duration": 45, "format": "JSON", "failure": 0.1},     # Recovery
        {"rate": 100, "duration": 15, "format": "syslog", "failure": 0.5}, # Critical: high rate + high ERROR
    ]

    for i, pattern in enumerate(patterns):
        print(f"Starting pattern {i+1}: {pattern['rate']} logs/sec, "
              f"failure-rate={pattern['failure']} for {pattern['duration']}s")

        process = subprocess.Popen([
            "python3", "fuzzy-train.py",
            "--lines-per-second", str(pattern["rate"]),
            "--log-format", pattern["format"],
            "--failure-rate", str(pattern["failure"]),
            "--output", "file",
            "--file", f"/tmp/logs/pattern-{i+1}.log"
        ])

        time.sleep(pattern["duration"])
        process.terminate()
        time.sleep(2)

if __name__ == "__main__":
    simulate_error_patterns()
Run the error pattern simulation:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
# Clean up any existing log files
rm -f /tmp/logs/*

# Create logs directory
mkdir -p /tmp/logs

# Make script executable
chmod +x simulate_error_patterns.py

# Run error pattern simulation
python3 simulate_error_patterns.py

# Monitor generated patterns
ls -la /tmp/logs/pattern-*.log
tail -f /tmp/logs/pattern-*.log

# Cleanup after simulation
pkill -f "simulate_error_patterns.py"
Troubleshooting Decision Tree
flowchart TD
    START[Log Generation Issue?] --> A{What's the problem?}

    A -->|Container won't start| B[Check Docker & Image]
    A -->|Permission denied| C[Fix File Permissions]
    A -->|High CPU usage| D[Reduce Generation Rate]
    A -->|Logs not appearing| E[Check Output Config]
    A -->|Agent not reading| F[Verify Log Shipping]

    B --> B1[Pull image & check logs]
    C --> C1[chown & chmod logs dir]
    D --> D1[Limit CPU & reduce rate]
    E --> E1[Verify file paths]
    F --> F1[Check agent config]

    B1 --> SUCCESS[Issue Resolved]
    C1 --> SUCCESS
    D1 --> SUCCESS
    E1 --> SUCCESS
    F1 --> SUCCESS

    style START fill:#e3f2fd
    style A fill:#e8f5e8
    style B fill:#fff3e0
    style C fill:#fce4ec
    style D fill:#f1f8e9
    style E fill:#e0f2f1
    style F fill:#f9fbe7
    style SUCCESS fill:#c8e6c9
Best Practices for Log Generation
Follow these log generation best practices for effective log aggregation testing:
- Start Small: Begin with low-volume fake log generation and gradually increase
- Monitor Resources: Watch disk space, CPU usage, and memory consumption during log generation
- Clean Up: Implement log rotation and cleanup procedures for generated logs
- Realistic Data: Use realistic timestamps and patterns for accurate log testing
- Version Control: Keep your log generation scripts and configurations in Git
- Test Incrementally: Validate each component before scaling up log generation volume
- Document Configurations: Maintain clear documentation of log generation parameters
- Security Considerations: Ensure fake logs don’t contain sensitive information
- Resource Planning: Calculate log generation volume requirements in advance
- Integration Testing: Test log shipping agents with various log formats
Conclusion
Generating fake logs is essential for testing log aggregation systems safely and effectively. This comprehensive log generation guide provides solutions for:
- Development environments - Test parsing and filtering logic with fake log data
- Performance testing - Validate system capacity using high-volume log generation
- Training scenarios - Provide realistic generated logs for learning
- Production preparation - Ensure systems handle expected log generation load
Key Takeaways for Log Generation
- fuzzy-train and flog are the leading log generation tools
- Docker-based log generation provides scalable testing solutions
- Kubernetes DaemonSet enables cluster-wide log generation
- Volume calculations help optimize log generation performance
- Log shipping configuration is crucial for end-to-end testing
Next Steps for Implementing Log Generation
- Choose the appropriate log generation tool based on your requirements
- Start with basic fake log generation and gradually increase complexity
- Integrate generated logs with your log shipping agents
- Monitor system performance and adjust log generation rates
- Implement log rotation and cleanup procedures for fake logs
Related Log Generation Resources
- fuzzy-train GitHub Repository - Versatile log generation tool (v3.0.0)
- fuzzy-train Observability Recipes - Copy-paste Standalone, Docker Compose & Kubernetes examples
- flog GitHub Repository - Fast fake log generator
- Fluent-bit Documentation - Log shipping agent configuration
- Vector.dev Documentation - Modern log processing pipeline
- Grafana Alloy Documentation - Log collection and forwarding
This log generation guide helps DevOps teams implement effective fake log generation for comprehensive log aggregation testing. For more DevOps and observability content, explore our logging category and DevOps guides.